

Solving Current AI’s
Biggest Blind Spot
Introducing World’s First Universal Interpretation Model
DISCLAIMER: This document has been prepared by Zwag AI LLC solely for discussion with potential partners. The information contained in this document has not been independently verified. No representation or warranty express or implied is made as to, and no reliance should be placed on, the fairness, accuracy, completeness or correctness of such information or opinions contained herein. None of the Company nor any of its respective affiliates, advisers or representatives shall have any liability whatsoever (in negligence or otherwise) for any loss howsoever arising from any use of this document or its contents or otherwise arising in connection with this document.
Language is the cognitive interface between human minds and the world.
It is how communities interpret, categorize and assign value to signals they encounter.
Modern AI models behave as though the world thinks in English, flattening cultural nuance and misaligning cognition.
|
Langage
|
Machine Learning Data usage
|
World population language usage
|
|---|---|---|
|
English
|
70%
|
17%
|
|
Chinese
|
10%
|
19%
|
|
Spanish
|
5%
|
7%
|
|
Other languages
|
15%
|
57%
|
How current LLMs handle each of the core language features
|
Feature
|
Status in LLMs
|
|---|---|
|
Semantics (Meaning)
|
Partially captured (Strong in English, biased)
|
|
Syntax (Structure)
|
Mostly functional
|
|
Morphology (Word Formation)
|
Limited accuracy
|
|
Phonology (Sound System)
|
Not modelled
|
|
Pragmatics (Context & Use)
|
Partial, English-centric
|
|
Lexicon (Vocabulary & Concepts)
|
Surface-level only
|
|
Prosody (Rhythm & Melody)
|
Not modelled
|
|
Discourse (Flow & Narrative)
|
Functional in English only
|
|
Orthography (Writing System)
|
Technically covered
|
|
Cultural Encoding
|
Largely missing
|
|
Occupational
|
Missing across languages
|
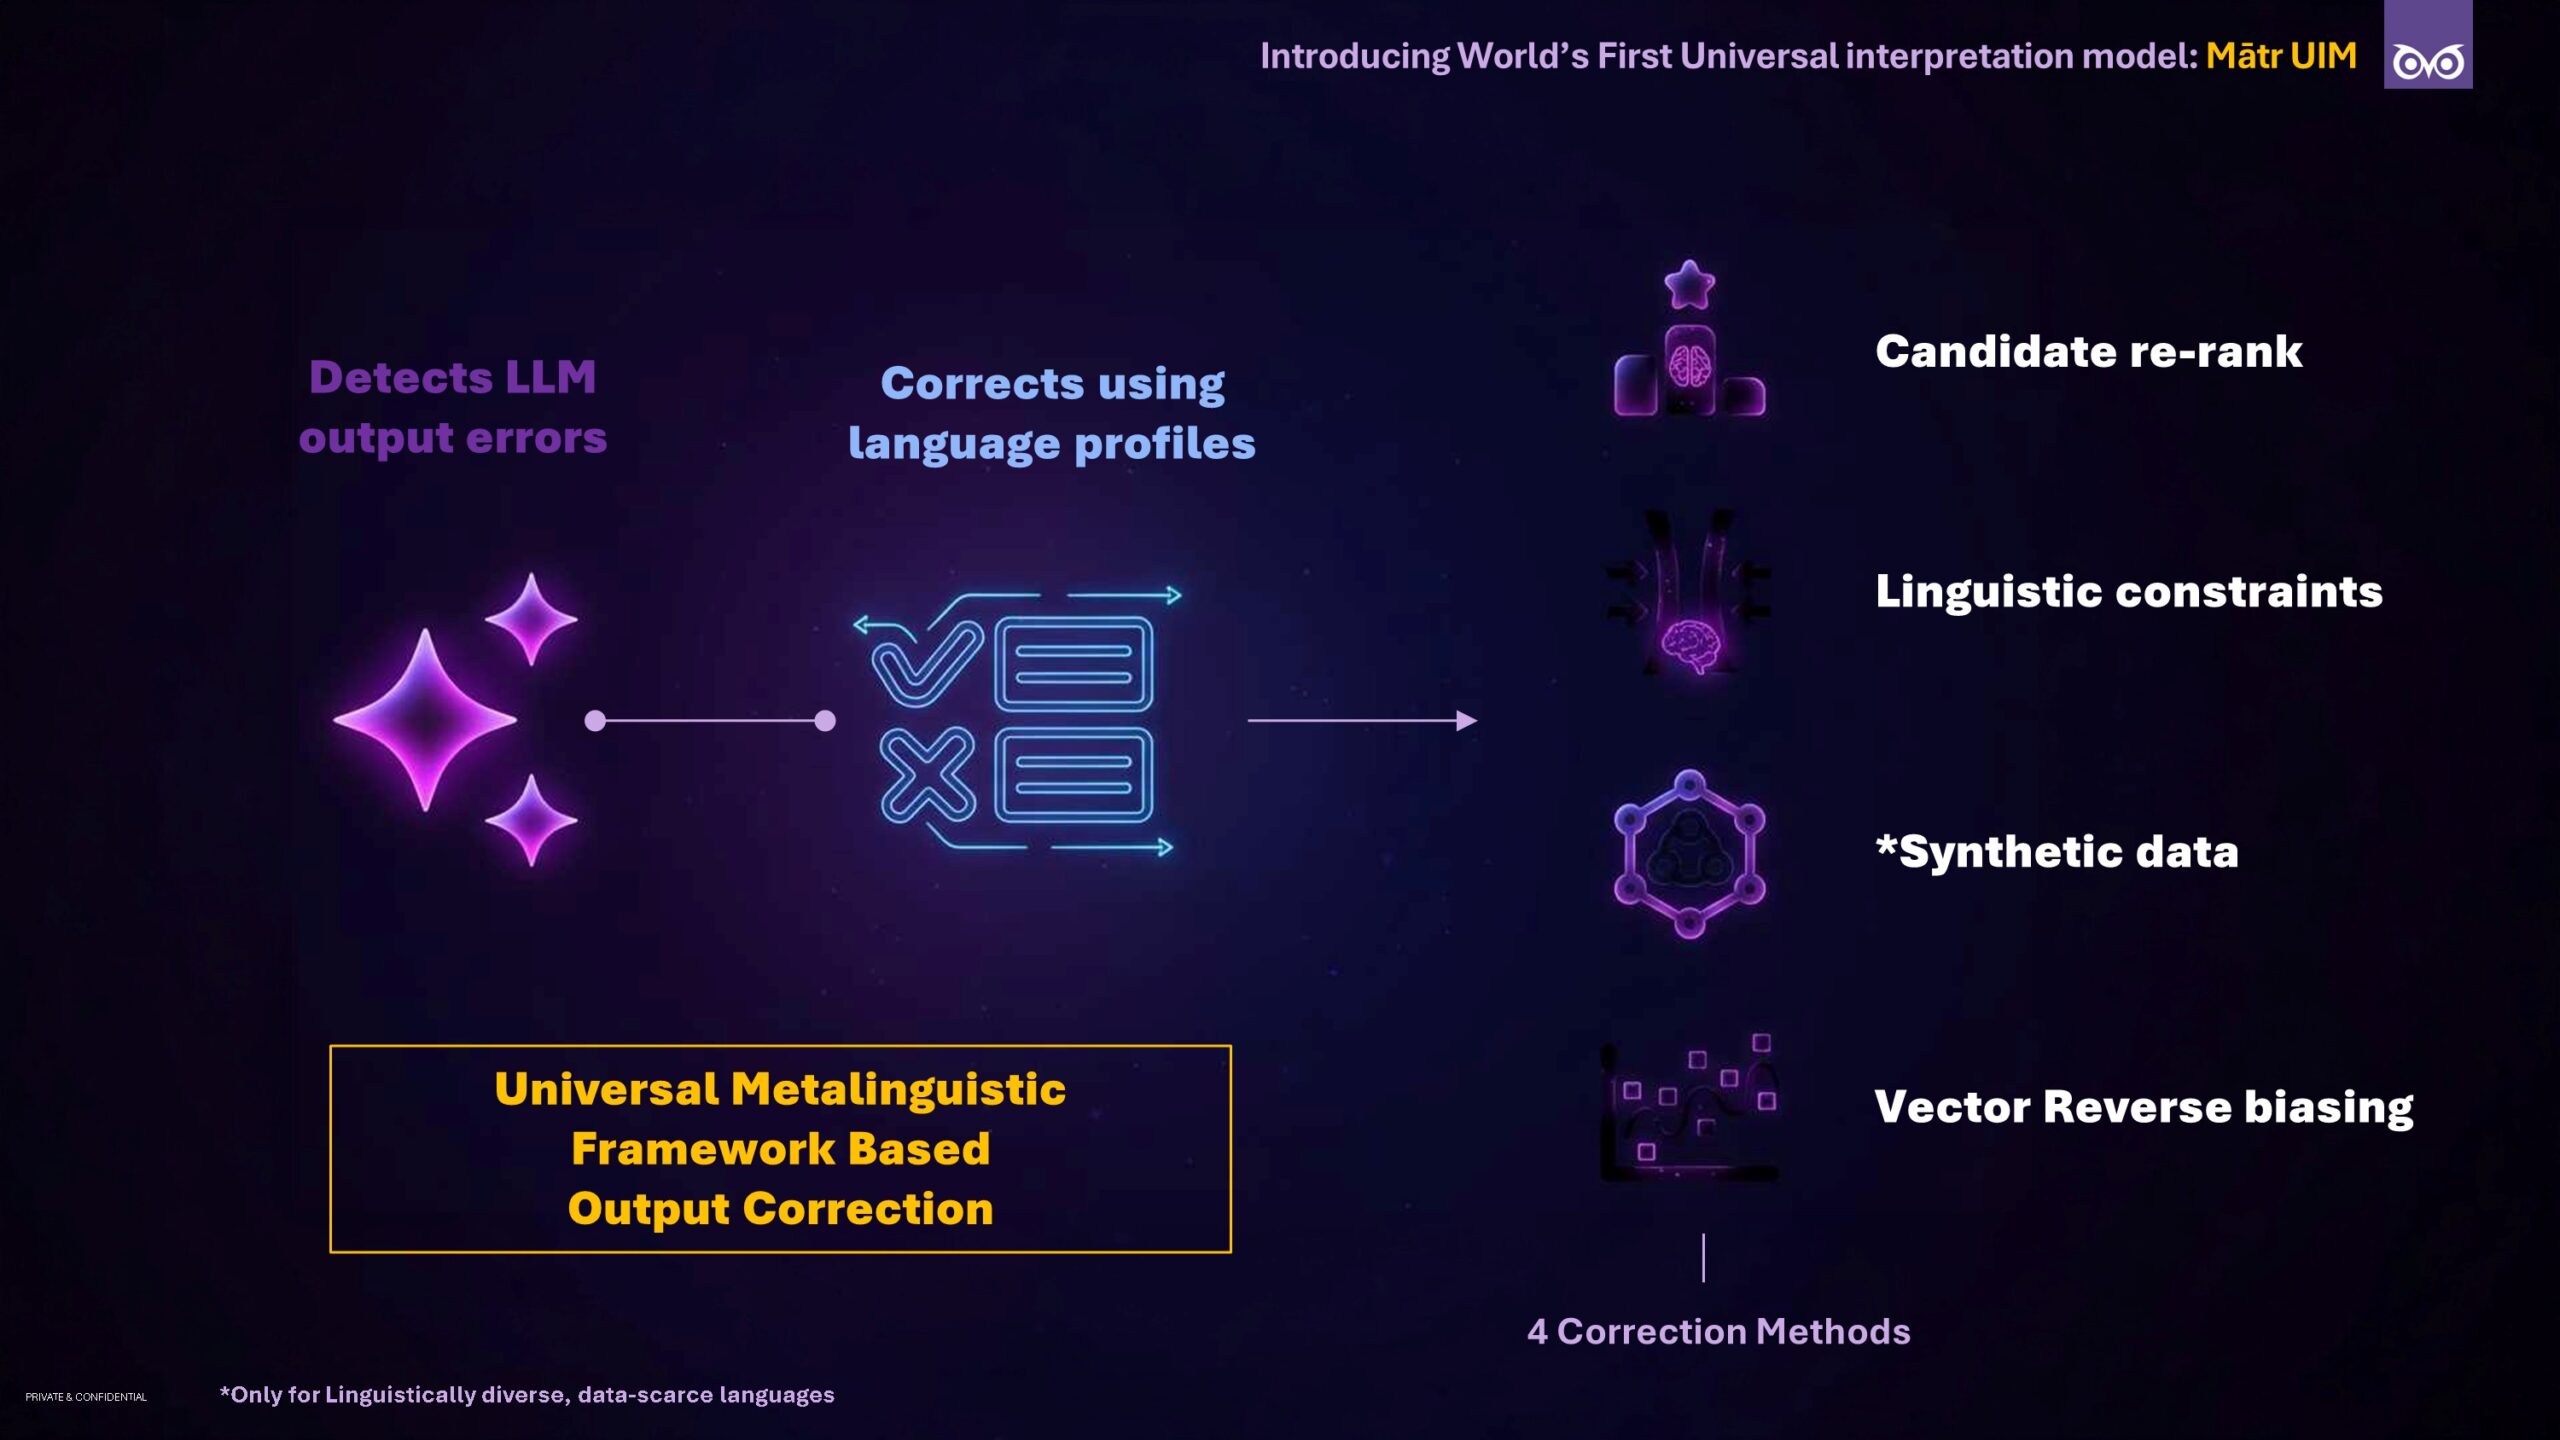
Introducing World’s First Universal interpretation model: Mātr UIM
The missing foundation of universal
cognition, that connects the
structural and cultural integrity of
every language it interacts with.
Instead of feeding LLMs more data, Mātr introduces
A METALINGUISTIC LAYER
that explicitly models
the internal logic of languages
- grammar, morphology, divergence and cognitive constraints.
It acts as a “translation BIOS” for
any model, aligning AI output
with the cognitive structures of
the target language.
Proof of Concept (POC)
|
Language
|
Errors Detected
|
Accurately Corrected
|
|---|---|---|
|
Chinese
|
3.23%
|
100.00%
|
|
Hindi
|
15.54%
|
84.91%
|
|
Thai
|
4.40%
|
20.00%
|
|
Japanese
|
7.33%
|
76.00%
|
|
Arabic
|
11.44%
|
79.49%
|
|
French
|
9.09%
|
80.65%
|
|
Swahili
|
9.68%
|
48.48%
|
|
Sinhala
|
45.16%
|
26.62%
|
|
Tamil
|
26.69%
|
29.67%
|
Proof of Concept (POC)
|
Region
|
AI macro upside (2030)
|
Language friction severity
|
Direct sector impact*
|
Potential additional AI capture via Mātr
|
|---|---|---|---|---|
|
Africa
|
∼$2.9 trillion
|
Very high
|
∼$30 billion in education, health and agriculture
|
+3–10 % → $87 B– $290 B
|
|
South Asia
|
Large (> $3 trillion)
|
Extreme (hundreds of languages)
|
∼$40–60 B (education, health, services)
|
+4–10 % → $140 B– $400 B
|
|
Southeast Asia
|
$1.0 trillion addition by 2030
|
High
|
∼$20–35 B
|
+3–8 % → $55 B– $175 B
|
|
Middle East & North Africa (MENA)
|
$320 B contribution by 2030
|
High (dialectal)
|
∼$15–30 B
|
+3–7 % → $45 B– $140 B
|
|
Latin America
|
AI forecast to add ≈5.4 % of regional GDP (~$0.5 T)
|
Medium
|
∼$15–25 B
|
+2–6 % → $40 B– $150 B
|
|
Indigenous / Minority regions
|
Not GDP-driven
|
Very high
|
∼$5–10 B (education & cultural sectors)
|
Policy-led strategic value
|
What ZWAG is building
ZWAG AI is a deep-tech AI company in DIFC focused on solving one of the most persistent structural problems in AI: making modern AI systems truly usable across the world’s languages, especially where today’s models systematically fail.
Our flagship product is Mātr, built on an internal framework we call the Universal Metalinguistic Framework (UMF).
What is Mātr
Mātr is a model-agnostic enabling layer that integrates with existing LLMs. We do not replace models, retrain them, or compete with foundation model creators. Instead, we increase their global usability, particularly in linguistically and culturally divergent languages.
POC
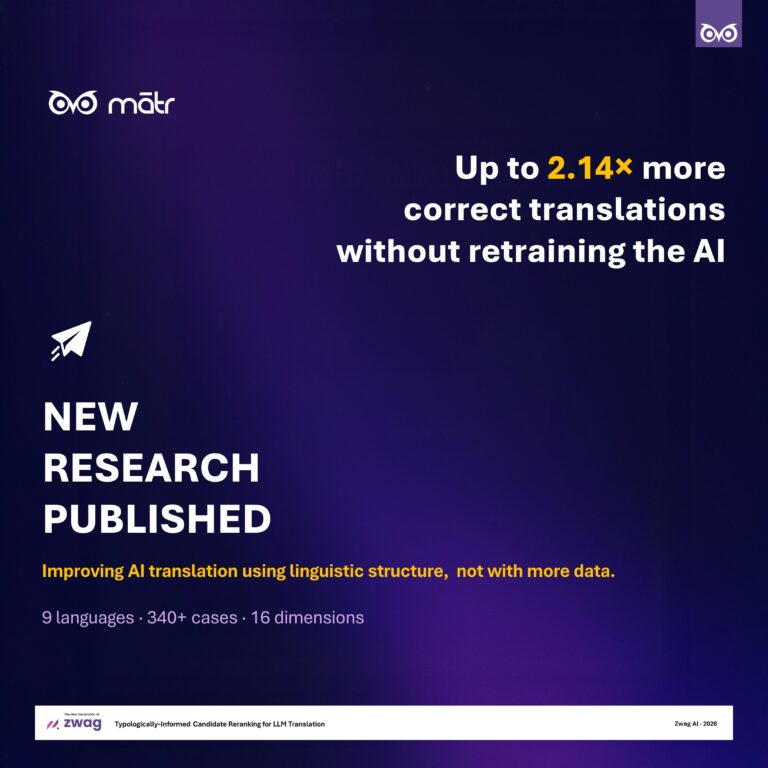
We posted our pre-print
Proof so far for Mātr
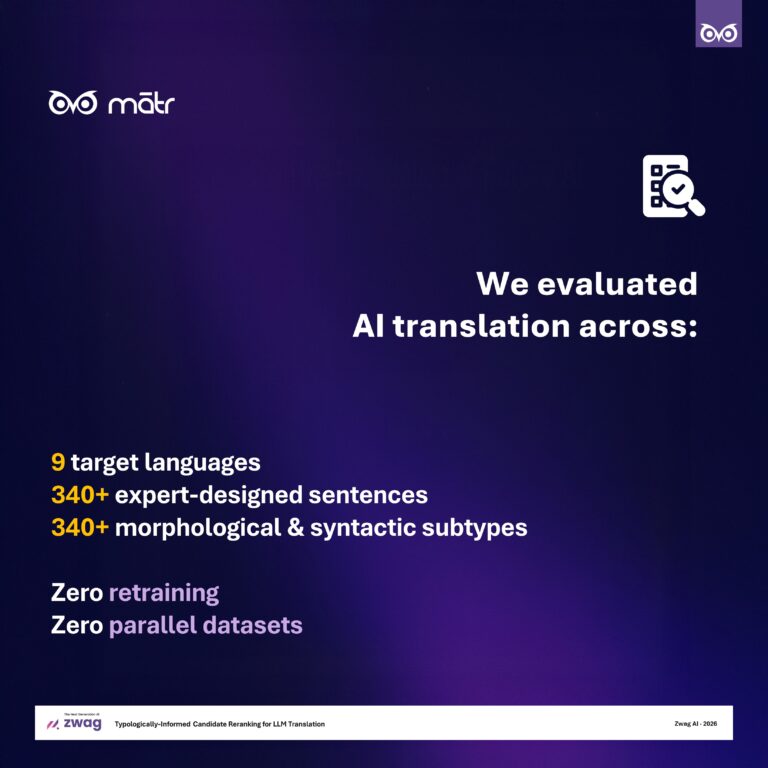
Tested across 9 languages
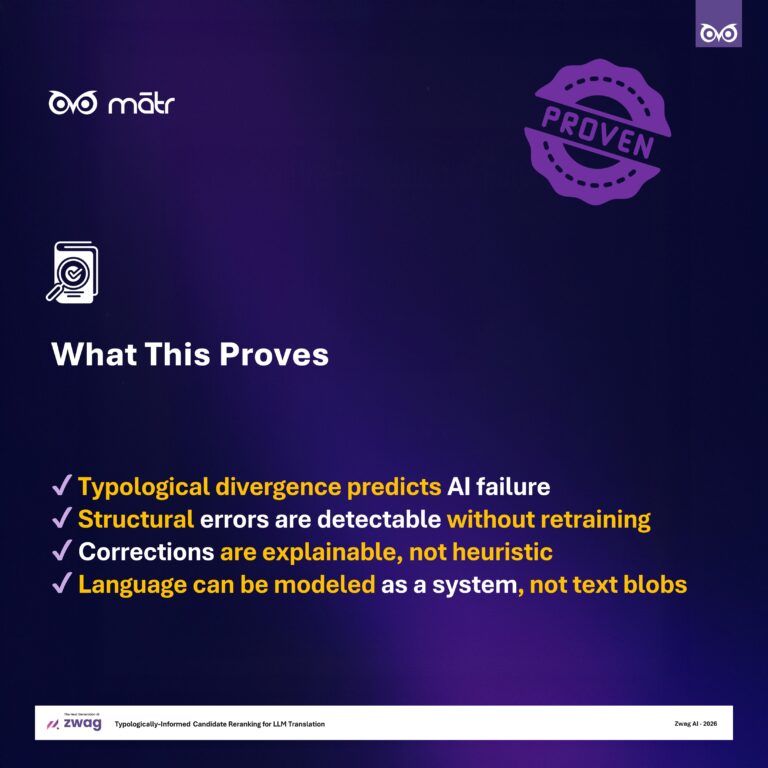
Detected ~15% semantic & morphological errors in ChatGPT (5.2) outputs
Corrected 60%+ of those errors
Achieved up to 2× improvement in correct interpretations - without retraining the model
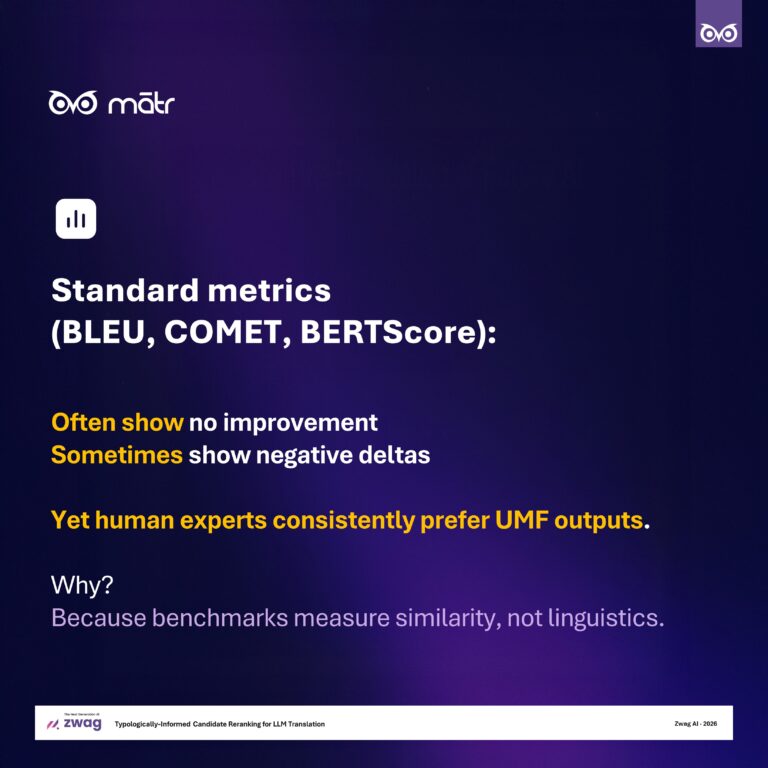
Our framework detected errors in LLM output that Existing Benchmarks like BLUE and COMET scores missed.
ASK
We are now going for two fundraising stages:
Pre-seed – US$250,000
Instrument: SAFE (preferred)
Purpose: expand typological dataset creation, strengthen the UMF → Mātr product layer, scale evaluation infrastructure, and prepare integration-ready pilots.
Seed – US$5,000,000
Instrument: priced equity round
Purpose: large-scale dataset expansion, production-grade platform build, enterprise and institutional deployments, and commercial partnerships with AI model creators and platforms.
Our Ask
$250,000 pre-seed round for 12-month proof of concept
Strategic guidance in AI partnerships and positioning
Not just another AI startup. We are a foundational infrastructure play.
Be part of the solution to AI's biggest blind spot
Bridging the Linguistic Gap in Large Language Models
|
Area*
|
What Linguists Bring*
|
Why It Matters Today*
|
What Mātr Does
|
|---|---|---|---|
|
1. Grammar Rules
|
How sentences are properly formed in each language
|
AI can sound fluent but still break real grammar rules
|
Makes sure AI follows the real structural rules of each language
|
|
2. Language Differences
|
How languages differ (word order, structure, logic)
|
AI often works best in English and struggles elsewhere
|
Adjusts AI output based on each language’s structure
|
|
3. Clear Standards of “Correct”
|
Expert-built language datasets and benchmarks
|
Fluency alone doesn’t mean correctness
|
Uses structured language standards to measure and improve AI accuracy
|
|
4. Error Detection
|
Tools to detect hidden grammar or meaning mistakes
|
AI can make subtle errors that look correct
|
Acts like a quality-control layer that catches structural issues
|
|
5. Low-Resource Languages
|
Expertise in languages with little digital data
|
Many languages are poorly supported by AI
|
Helps stabilize and support underrepresented languages
|
|
6. Explainability
|
Clear language to describe what’s happening in a sentence
|
AI systems are often black boxes
|
Explains why corrections are made in human language terms
|
|
7. Meaning Accuracy
|
Understanding how meaning is built logically
|
AI sometimes confuses related words with real meaning
|
Improves logical consistency and meaning structure
|
|
8. Context & Conversation Flow
|
How meaning changes with context
|
AI often fails across longer conversations
|
Extends checks beyond single sentences into full context
|
|
9. Dialects & Variation
|
Understanding slang, identity, dialect differences
|
AI tends to standardize and erase variation
|
Supports language diversity instead of flattening it
|
|
10. Language Preservation
|
Structuring endangered languages
|
AI risks ignoring smaller languages
|
Builds tools that can support language preservation
|
*Resource used: Linguistics as Foundational to NLP (RELIES framework), On Limits of LLM Fluency / Structural Competence
Why This Gap Exists - And Why Mātr Matters
In recent years, AI systems like large language models have become extremely fluent. They can write essays, translate text, and hold conversations that sound natural.
Because of this success, many people assumed that AI no longer needs linguistic expertise. The thinking became: “If the model sees enough data, it will learn language on its own.”
And to some extent, that works.
But there’s a hidden problem.
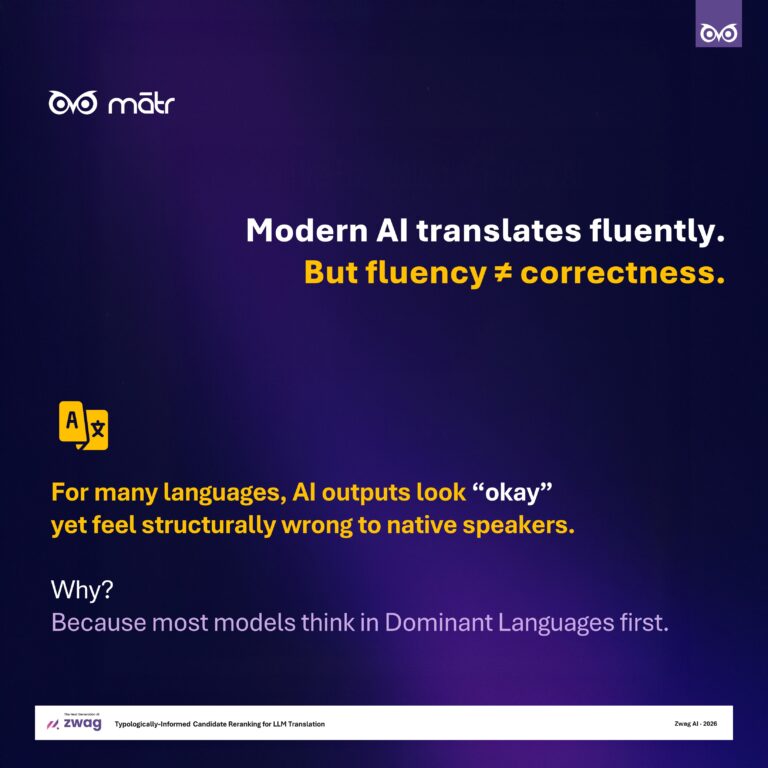
Fluency is not the same as structural correctness or true understanding.
AI models learn by predicting the next likely word. They do not actually know the structural rules of different languages. They do not understand how grammar varies across cultures. They do not naturally handle low-resource languages well. And they often fail in subtle ways, especially in meaning, context, and cross-lingual consistency.
This is where the gap appears.
Modern AI is powerful at pattern prediction.
But it lacks a structural layer that ensures linguistic accountability.
Recent research shows that even today, AI systems still rely heavily on linguistic knowledge for:
- Proper evaluation
- Cross-language stability
- Low-resource language support
- Interpretability
- Meaning accuracy
However, this linguistic knowledge is mostly used after models are built, for testing and fixing them.
Mātr changes that.
Instead of treating linguistics as something used only for evaluation, Mātr integrates linguistic structure directly into how AI outputs are checked, corrected, and stabilized.
In simple terms:
Most AI models guess what sounds right.
Mātr makes sure what sounds right is also structurally correct.
It works alongside linguists and language experts to bring structural intelligence back into AI systems, not by replacing neural networks, but by strengthening them.
This is not about going backward to rule-based AI.
It is about adding a structural governance layer that modern AI currently lacks.
And that is the gap Mātr is solving.
Let’s Talk Possibilities
Stay Connected
Subscribe to our Investor Newsletter to receive updates on milestones, funding rounds, and exclusive opportunities.
Contact Us
Let’s Build the Future Together
Feel free to reach out. Our team is ready to explore meaningful collaborations and respond to your inquiries with thoughtfulness and prompt attention.
At Mātr, we’re not just building technology - we’re reshaping how the world understands itself. Every collaboration is a step toward a more connected, intelligent future.
Priya M Nair
Founder & CEO